AI Agent Data Boundaries: Minimization, Redaction, and Retention
How to keep AI agent workflows useful without copying too much sensitive context into prompts, tools, logs, memory, checkpoints, or review surfaces.
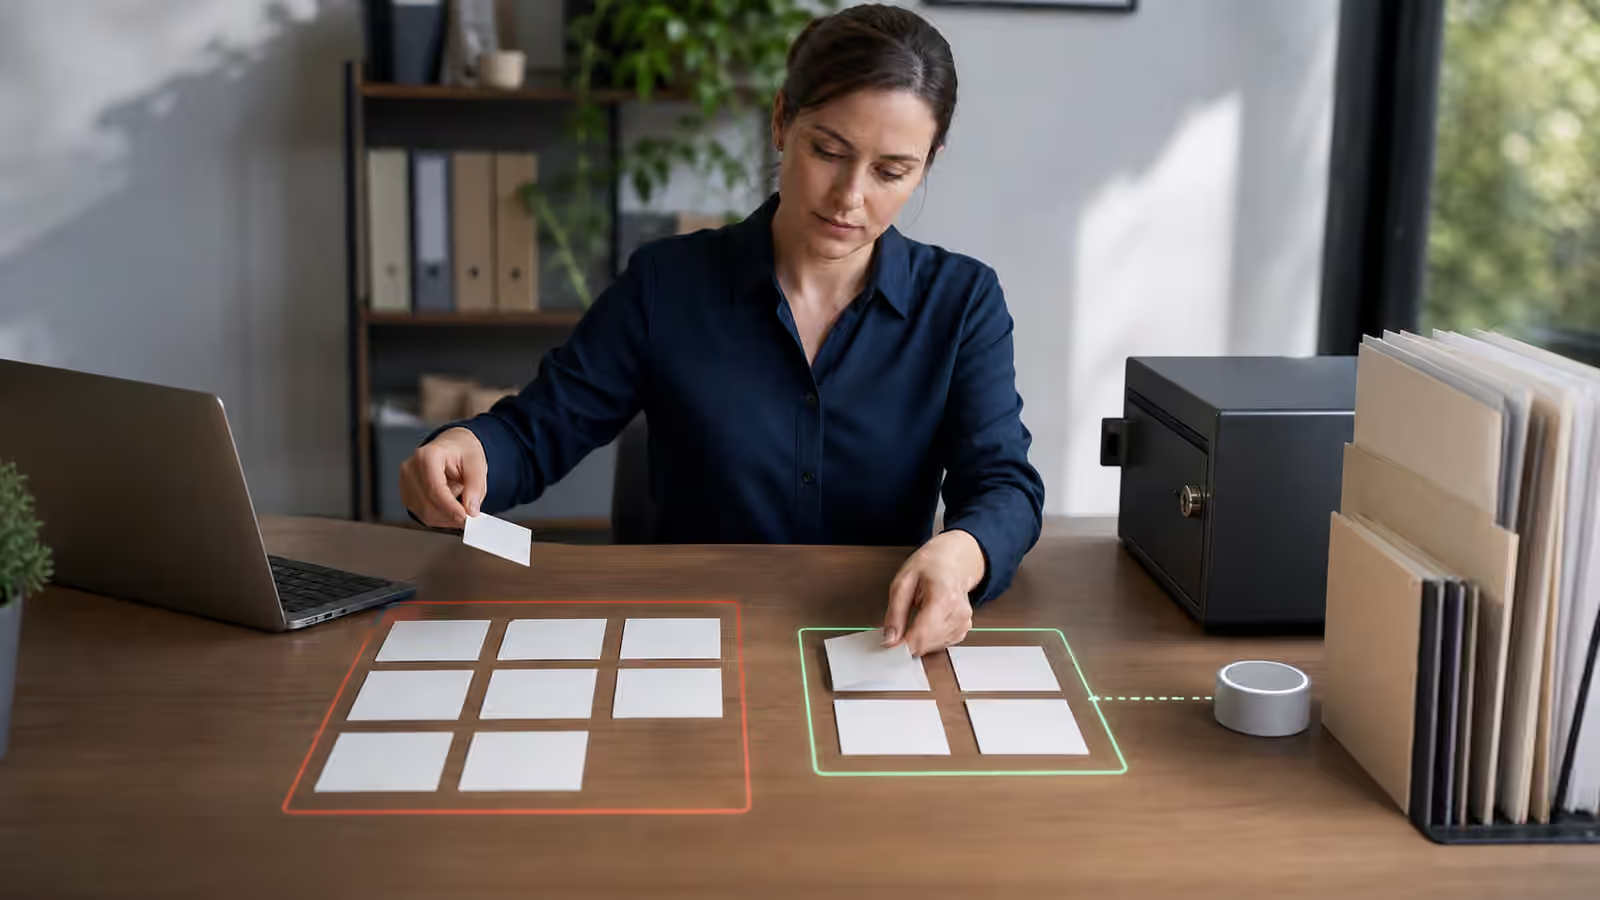
AI agents work by seeing enough of a task to act on it. That useful fact creates an uncomfortable habit: people keep giving the agent more context because more context feels safer. A support ticket gets the whole account history. A research assignment gets the entire document archive. A coding task gets logs, chat excerpts, customer examples, and production traces. The agent may perform better, but the workflow has quietly copied material into places where it may not belong.
Data boundaries are the discipline of deciding what an agent may see, what it may carry forward, what it must hide from later surfaces, and what it should forget when the task ends. They are not only a privacy concern. They affect quality, review burden, security posture, incident response, and whether people trust the system enough to use it for real work.
The point is not to starve the agent. A delegate with no context becomes a guessing machine. The point is to make context intentional. An agent should receive enough material to do the job, not every field that happens to be reachable from the job. The difference sounds small until the workflow touches customer records, employee notes, private messages, credentials, legal drafts, financial details, health information, unpublished plans, or personal preferences that were never meant to become general memory.
Minimum useful context
Minimum useful context is the agent version of least privilege. Instead of asking which systems the agent could access, it asks which facts the current task actually requires. A calendar agent may need meeting times and participant names, but not every private note attached to those meetings. A support agent may need the order status and approved policy, but not the customer’s full payment history. A coding agent may need a failing test log, but not a production secret that appeared nearby in the environment.
This connects directly to AI Agent Context Windows and Working Sets . A context window is not a neutral container. It is an active working set that shapes the agent’s choices. If irrelevant sensitive material is present, the agent may quote it, summarize it, log it, store it, or use it as evidence for a decision that did not require it. Even when the model behaves well, the trace and review surface may now contain data that would have been better left out.
Minimum useful context should be designed before the agent run begins. The workflow can decide that the agent receives a customer-safe account summary rather than raw records, a redacted transcript rather than the whole conversation, or a policy excerpt rather than a full internal handbook. In many cases, the best data boundary is upstream of the model: a tool or retrieval layer that only returns fields appropriate for the task.
For a support reply about a delayed shipment, for example, the tool might return an opaque case reference, the shipment status, the elapsed time, and the relevant policy version. It can leave out the payment details, street address, and unrelated ticket history. The agent drafts a reply for review; an authorized support tool resolves the case reference when the reviewer needs the original record. If the shipping region changes the policy, include the region rather than the full address. If a necessary fact is missing, the agent should ask for a narrowly scoped lookup instead of guessing or fetching the whole account.
Write this boundary as a small contract: the task and permitted purpose, the fields and sources allowed, the intended recipients, the systems that will receive the data, and the owner who can approve an exception. Check the actual tool response and configured access, not just the prompt. Consider model and tool providers, integrations, and their configured retention and data-use settings before sending the working set to them. AI Agent Access Reviews helps keep those permissions aligned with the current task.
Enforce that contract at retrieval, using the requesting user’s and task’s actual permissions. A shared agent service account may be able to read more than the person receiving its answer; its access alone is not proof that a particular record is appropriate to return. Apply the same check to search results, cached passages, attachments, and follow-up lookups. If the authorized view cannot supply a required fact, stop or escalate rather than widening access by default.
Redaction should preserve meaning
Bad redaction destroys usefulness. If every name, timestamp, amount, and identifier is removed, the agent may no longer understand the sequence of events. Good redaction removes unnecessary exposure while preserving the shape of the work. The agent may not need a customer’s real name, but it may need to know that the same person wrote two messages. It may not need a full address, but it may need the shipping region. It may not need a complete account number, but it may need a stable reference that lets a human reviewer connect the draft to the right record without exposing the record broadly.
This is why redaction is better treated as transformation than deletion. Replace specific values with consistent placeholders when continuity matters. Keep relative timing when order matters. Preserve source labels when authority matters. Keep enough structure that the agent can reason, but remove details that do not affect the decision. A support workflow can show “customer A,” “order 392,” and “policy record 14” inside the agent run while keeping the underlying private fields behind controlled tools.
Those labels are not necessarily anonymous. A stable placeholder can link records across a run, and an unusual combination of dates, location, and events can identify someone even after names are removed. Use run-scoped random references where cross-run linking is unnecessary, protect any mapping separately, and check whether an identifier such as an order number is itself sensitive or usable to retrieve a record. NIST’s guidance on de-identifying government data describes the risk of re-identification and the need to assess the intended use and disclosure model.
Test the transformation with approved synthetic fixtures that include names in free text, attachments, alternate spellings, identifiers in URLs, and relevant details next to sensitive ones. Inspect both what reaches the model and what appears in outputs and logs. Automated detectors can miss data or remove important context; route uncertain or failed transformations to an authorized reviewer or stop the run, rather than silently passing the original through. Recheck representative cases when source formats or tools change. AI Agent Test Fixtures can help make these checks repeatable.
For a synthetic shipment case, a useful check might require the transformed input to retain customer A, region: north, status: delayed, and the policy version while excluding the fake name, street address, and payment reference from the model input, draft, trace, and checkpoint. Include a second case whose policy depends on the region: removing that field should cause a narrow lookup or escalation, not a confident answer. Check extracted attachment text and error responses too. These cases reveal both missed redactions and transformations that break the task; passing them does not prove all sensitive data will be detected.
AI Agent Tool Contracts are especially useful here because tools can carry redaction rules in their shape. A customer lookup tool can return a limited support view instead of a database row. A document retrieval tool can mark a passage as restricted and return a short approved summary. A message drafting tool can refuse to include fields that are not allowed in an outbound channel. The agent still reasons over useful evidence, but the tool prevents raw exposure from becoming the default.
Sensitive data changes the whole run
Once sensitive material enters an agent run, it does not stay in one place. It can appear in the prompt, a tool input, a tool output, a trace, a checkpoint, a human review panel, a final answer, a memory store, an evaluation artifact, or an incident report. A person may think they only pasted a private note into the task, but the workflow may preserve that note in several downstream systems.
That is why data boundaries should follow the path of the run rather than only the initial prompt. If the agent reads restricted material, the trace should not automatically expose the full text to every reviewer. If a checkpoint is created, it should preserve references, decisions, and unresolved questions without copying unnecessary sensitive excerpts. If the agent drafts a customer message, the draft should be checked for fields that were useful internally but inappropriate externally.
AI Agent Checkpoints and AI Agent Observability both depend on this distinction. A checkpoint should make work resumable without becoming a second archive of private material. A trace should make work accountable without becoming a surveillance dump. The reviewer needs to know that a restricted source was used, why it mattered, and what decision came from it. The reviewer does not always need the raw source itself.
Apply filtering before a trace or checkpoint is stored, including on error and retry paths; hiding a field in the review interface does not remove the stored copy. Record a safe source reference, tool name, time, decision, and outcome where those are needed, while controlling access to the underlying evidence. OWASP’s logging guidance identifies secrets and sensitive personal data as examples that generally should not be recorded directly. For credentials specifically, use the stricter controls in AI Agent Secrets Handling .
Memory is not a storage closet
Longer-lived memory makes agents more useful, but it also raises the cost of sloppy data handling. A preference, policy, project fact, or prior decision can help future work. A private detail that only mattered once can become a quiet liability if it is saved and reused later. The problem is not only exposure. It is drift. A sensitive fact can become stale, inferred beyond its original context, or applied to a task where it no longer belongs.
AI Agent Memory and Context frames memory as something that needs provenance and forgetting. Data boundaries make that concrete. A memory should say where it came from, why it is useful, how broad its use should be, and when it should be reviewed or removed. If a fact came from a restricted document, it should not become a general-purpose preference. If a temporary exception was approved for one task, it should not become a standing rule.
The safest default is that task data does not become memory unless the workflow has a clear reason. Agents can remember durable preferences, accepted decisions, stable project facts, and approved operating rules. They should be much more cautious with private messages, customer specifics, one-off negotiations, temporary credentials, health or financial details, and anything inferred from behavior rather than stated as a reusable fact.
Data boundaries reduce prompt injection risk
Prompt injection is often described as hostile text trying to control the agent. Data boundaries add another angle: the less unnecessary material the agent reads, the fewer untrusted instructions it has to ignore. A broad document dump may contain hidden instructions, stale guidance, copied prompts, old macros, or vendor language that sounds authoritative. A narrower, labeled working set makes it easier for the agent to treat source material as evidence rather than command.
AI Agent Prompt Injection explains the content-versus-authority problem. Data boundaries help enforce that distinction at intake. A tool can mark a web page as untrusted source material. A retrieval layer can separate approved policy from user-submitted text. A review surface can show that the agent relied on a governed source rather than a random passage that happened to match the question.
The goal is not to pretend redaction solves prompt injection. It does not. A small piece of hostile content can still be dangerous if the agent has broad authority. But minimizing and labeling data lowers the number of confusing instructions in the working set and makes it easier to review why the agent acted.
Review surfaces need levels of detail
Human review often fails when it shows either too little or too much. Too little, and the reviewer cannot tell whether the agent used the right evidence. Too much, and the reviewer has to sort through private material that the decision did not require. A good review surface gives levels of detail: a plain outcome, the sources used, the fields exposed, the sensitive sources withheld, and a controlled path for authorized reviewers to inspect more if needed.
This connects to Human Review for AI Agents . The handoff should say what the agent touched and what remains uncertain. For data-sensitive work, it should also say what was deliberately not exposed. That omission is not a gap. It is part of the design. “The agent used a restricted billing summary and did not expose payment details in the draft” is a stronger handoff than a polished answer that leaves the reviewer guessing what entered the run.
Review surfaces should also distinguish internal evidence from external output. An agent may use private context to make a decision, but it should not automatically reveal that context in the message it sends, the report it writes, or the ticket comment it leaves. The boundary between “needed for reasoning” and “appropriate to repeat” is one of the most important data lines in agent design.
Before an output crosses into a different audience or tool, check it against that destination’s allowed fields and recipient access. That includes citations, filenames, links, quoted snippets, and tool arguments, not just the final paragraph. A filter or human review can catch some disclosures, but neither is a guarantee; prevent unnecessary access upstream as well. OWASP’s sensitive information disclosure guidance notes that prompt instructions alone may not reliably prevent disclosure.
Retention should be decided before launch
Retention is easy to postpone because it feels administrative. It is not. If agent traces, prompts, tool outputs, checkpoints, generated drafts, and review comments are kept forever by default, the system accumulates an expanding shadow archive of delegated work. That archive may be useful for debugging and evaluation, but it should not grow without purpose.
Retention policy should match risk and utility. Short-lived low-risk drafts may not need long retention. Evaluation cases may need preserved artifacts, but those artifacts can often be redacted or synthesized. Incident records may need enough evidence to understand what happened, but not every raw input copied into every report. Operational metrics can often be aggregated without retaining sensitive content. The exact retention period depends on the organization and the domain, but the engineering habit is stable: decide what is kept, why it is kept, who can see it, and when it expires.
For each store, name an owner, a retention period or review date, and the deletion method. Include caches, exports, provider-held records, and backups in the inventory; deleting a memory entry or the visible conversation does not necessarily erase those copies. Verify expiry and deletion with the systems involved, document backup limitations and schedules, and account for applicable legal holds or other retention obligations. The UK ICO’s storage limitation guidance discusses retention reviews, pseudonymized data, and backups; the rules applicable to a particular workflow depend on its jurisdiction and circumstances.
AI Agent Incident Response becomes easier when retention is intentional. After a failure, the team needs evidence. If everything was deleted immediately, learning suffers. If everything was kept broadly, the incident may create a second exposure. A deliberate boundary keeps enough proof to repair the system without preserving every private detail as a permanent artifact.
If a boundary fails, pause the affected workflow or destination, notify the designated incident owner, and identify the data, recipients, and stores involved. Preserve necessary evidence under restricted access before removing copies, then follow the organization’s incident and notification procedures. Where a credential was exposed, revoke or rotate it through the appropriate owner. Verify remediation in the affected stores and add a sanitized regression case for the failure; deleting the visible output alone may leave traces or exports behind.
The operating habit
Data boundaries turn privacy from a warning into a design practice. At intake, the workflow asks what the agent actually needs. At retrieval, tools return limited, labeled, task-shaped views. During execution, traces and checkpoints preserve evidence without unnecessary copying. At review, people see enough to judge the work without being flooded with sensitive source material. At memory time, only durable and approved facts survive. At retention time, old artifacts expire when their purpose is gone.
This habit does not make agents risk-free. It makes the risk easier to see and manage. AI Agent Permissions decides what the agent may do. Data boundaries decide what the agent may know, repeat, store, and show. Serious systems need both.
The practical test is simple. After an agent run, a reviewer should be able to answer what data was used, why it was needed, where it appeared, what was redacted, what was retained, and what should be forgotten. If those answers are visible, the workflow is becoming governable. If nobody can answer them, the agent may still be helpful, but its data trail is doing more work than anyone has admitted.