AI Agent Source Provenance: Keeping Evidence Attached to the Work
How to keep source evidence, tool results, uncertainty, and version context attached to AI agent outputs so reviewers can see where claims came from.
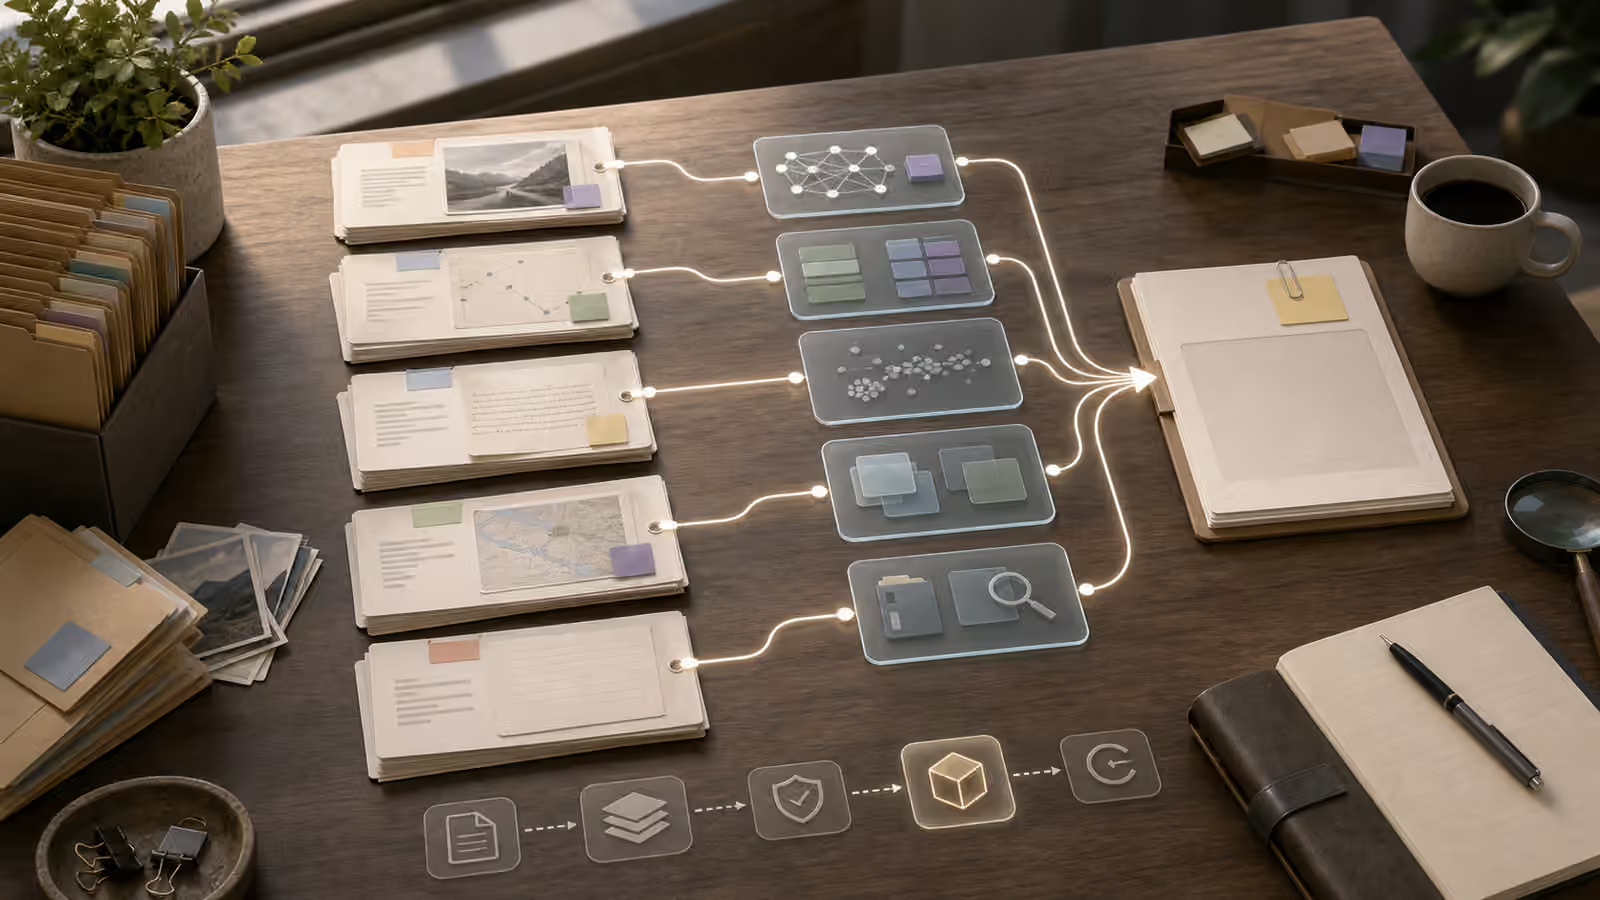
Agent work becomes fragile when evidence falls away from the answer. A delegate reads a source, calls a tool, compares records, drafts a polished summary, and hands back a result that sounds complete. The reviewer may see the conclusion, but not the path. They do not know which records were inspected, which sources were skipped, which facts were inferred, which claims are current, or which uncertainty was smoothed over by fluent language.
Source provenance is the discipline of keeping evidence attached as work moves through an agent run. It is related to AI Agent Knowledge Bases and AI Agent Output Verification , but it is not the same thing. Grounding helps the agent find approved material. Verification checks the final work. Provenance preserves the trail between those two moments, so a reviewer can see why the output says what it says.
Provenance Begins Before Writing
The simplest way to lose provenance is to treat sources as temporary reading material. The agent searches, reads, remembers, and then writes from memory. That mirrors how people sometimes work, but agents need a more explicit habit because their final prose can sound equally confident whether the supporting evidence was strong, weak, stale, or missing.
A provenance-aware workflow records source identity as soon as the source enters the run. A policy document has a title, location, owner, and revision date. A ticket has an identifier, timestamp, requester, and status. A tool result has a tool name, input, output, and time of retrieval. A web page has a URL and access time, but also a trust level if the workflow distinguishes approved sources from open research. These details do not all need to appear in the final article, email, report, or code review note. They do need to remain available.
This is why AI Agent Tool Contracts should return boring, inspectable metadata. A search tool that returns only snippets asks the agent to improvise the evidence trail later. A search tool that returns stable IDs, source types, dates, and confidence boundaries makes provenance easier by default. The agent should not have to remember to invent a citation system after the fact. The workflow should give it evidence objects it can carry forward.
The W3C PROV primer describes a useful model: entities such as documents, activities that use or produce them, and the people or systems associated with those activities. A workflow does not need to implement the whole standard to benefit from the distinction. Record the source, the retrieval or transformation, and the resulting artifact as separate things, so a reviewer can follow the path between them.
Claims Need Different Kinds Of Support
Not every sentence in an agent artifact needs the same source treatment. A factual claim about a customer record should point back to the record. A recommendation should point to the evidence and reasoning that support it. A statement about uncertainty should preserve what was missing. A summary of a meeting may need speaker attribution, while a summary of a code change may need file paths, test results, and diffs.
Provenance becomes more useful when it matches the claim. If a support agent writes that a shipment is delayed, the reviewer needs to know which system reported the delay and when it was checked. If a research agent writes that two policies conflict, the reviewer needs both policy references and the conflicting clauses summarized accurately. If a coding agent writes that tests passed, the reviewer needs the command, environment, and relevant result, not a vague assurance.
This is where structured artifacts help. AI Agent Structured Outputs explains how schemas make delegated work usable downstream. Provenance fields can be part of that schema. A claim can carry a source ID. A recommendation can carry supporting evidence and known limits. A draft can carry citations separately from prose. The structure does not have to be heavy, but it should make it hard for unsupported claims to hide inside a smooth paragraph.
Build a small evidence record
For each consequential claim, keep a reference to the source and the specific passage, field, or result that supports it. A practical record can include:
- Claim and status: The statement being supported, marked as directly reported, calculated, inferred, or unresolved.
- Source and location: A stable document or record ID and a page, section, field, or line reference. Include a link when the reviewer can use it.
- Version and time: The revision, effective date, commit, or report period when available, plus when the source was retrieved. A retrieval time is not the same as an effective date.
- Method and limits: The tool and relevant query or command, whether the result was complete, and any assumptions, conflicts, or failed lookups.
- Review path: Where an authorized reviewer can inspect the evidence, who can resolve an open question, and whether the claim was checked.
For example, a draft support note might say: “Order 123 is shown as delayed as of 10:00 UTC; the expected delivery date is not confirmed.” Its internal evidence record could point to order 123 in the shipping system, the status field and retrieval time, and a failed carrier lookup. The first part is a reported system status; the second is an unresolved question, not proof that no delivery date exists. Before relying on the note, a reviewer can open the record and check that the status still applies. If the result was cached or partial, record that too.
Use an internal identifier in a wider handoff when the underlying order details are sensitive. Avoid copying credentials or unnecessary personal data into the evidence record. AI Agent Data Boundaries and Redaction covers how to choose what can move between systems and reviewers.
Follow a calculation back to its inputs
A source list at the end of a report may not show which source supports which sentence, or how a calculation was made. Link each consequential claim to its inputs and preserve the transformation between them. For an illustrative monthly variance note, the trail might look like this:
| Part of the trail | Record for the reviewer |
|---|---|
| Source | Report R1, approved April actuals, version 3, revenue field: $120,000; report R2, approved April budget, version 2, revenue field: $100,000. |
| Calculation | (120,000 - 100,000) / 100,000 = 20%; same currency and reporting period. |
| Claim | “April revenue was 20% above budget,” labeled calculated and linked to R1 and R2. |
| Limit | Neither report establishes why revenue changed. A proposed explanation needs separate evidence. |
In a real handoff, the identifiers should resolve to the relevant fields or protected report versions, and the record should include retrieval times and any adjustments or exclusions. A reviewer can check the inputs, units, formula, and rounding without accepting the agent’s conclusion on trust. If an input is missing or the budget is zero, leave the percentage unresolved rather than inventing a value or dividing by zero.
When one agent summarizes a source and another writes the report, preserve links from the final claim through the summary to the original passage. Label the summary as a derived artifact, not an independent source. If the source cannot be opened or the link between a claim and its evidence is lost, mark that claim for review. Several summaries of the same report do not constitute independent corroboration.
Tool Results Are Evidence, Not Decoration
Tool calls often become invisible in final agent output. The agent reads a file, runs a command, queries a database, or checks a queue, then reports a conclusion. If the conclusion is correct, nobody notices the missing trace. If the conclusion is wrong, the team has to reconstruct the run from logs or a transcript.
A better pattern treats tool results as evidence objects. When a tool returns a result, the agent should be able to reference it later. When a reviewer inspects the artifact, they should be able to see the relevant tool result without reading the entire conversation. AI Agent Observability covers the broader trace. Provenance is the part of that trace that remains attached to the work product.
This matters in ordinary workflows. A recruiting agent might screen inbound applications against role requirements. The final output should not merely say that a candidate appears to match. It should show which requirements were checked, where the evidence came from, and which items remain unverified. A finance operations agent might prepare a variance note. The final note should preserve the ledger period, report version, and assumptions used. A coding agent might update a dependency. The handoff should preserve the changed files, test commands, lockfile behavior, and any warnings that still matter.
Without this attachment, human review becomes theater. The reviewer is asked to approve a confident artifact while the evidence lives somewhere else, if it exists at all.
Preserve Uncertainty As Carefully As Facts
Agents often fail by turning uncertainty into tone. They choose a likely answer, write it gracefully, and leave the reviewer with no obvious sign that a source was missing or a conclusion was inferred. Provenance should preserve uncertainty with the same care it gives confirmed facts.
If a source was not found, that absence belongs in the trail. If a tool returned a partial result, the partial boundary should remain visible. If two sources disagreed, both should be named. If the agent relied on a stale document because no current source was available, the artifact should say so. This is not clutter. It is the difference between a reviewer correcting the work and a reviewer trusting the wrong level of certainty.
Record what was searched and any access or tool failures before describing a source as missing. An empty result from a limited query, a permission denial, and a complete search have different implications. When sources disagree, preserve each source’s scope and status and use the source conflict resolution guide to decide whether the work can proceed.
When AI Agents Fail becomes easier to apply when uncertainty has been preserved. A bad answer may come from a weak source, a missing source, a mistaken inference, a tool failure, or a reviewer expectation that was never made explicit. Provenance gives those failure modes a place to show up. Without it, every error looks like a mysterious model problem.
Uncertainty also helps downstream agents. In a coordinated workflow, one delegate may gather evidence and another may draft the final artifact. If the first delegate passes uncertain material without labels, the second may polish it into apparent fact. AI Agent Coordination depends on handoffs that preserve what is known, what is inferred, and what needs human judgment.
Version And Freshness Matter
Sources change. Policies are revised. Tickets are updated. Files are edited. Search results shift. A source trail without version context can be misleading even when every citation is real.
Evergreen provenance does not require fragile claims about which product, model, or tool is best at a given moment. It requires honesty about retrieval. The agent should know when a source was accessed, which version or timestamp mattered, and whether the workflow treats the source as durable. A static internal policy may be stable enough to cite by version. A live customer record may need a retrieval timestamp. A repository file may need a commit or branch. A generated report may need its run ID.
This version discipline connects provenance to AI Agent Change Management . If an agent workflow changes its source set, retrieval method, or citation format, reviewers should be able to compare old and new behavior. If a source becomes stale, the agent should not silently keep using it because it appeared in memory. Provenance should make freshness visible enough that stale grounding can be corrected.
A version identifier helps find the material that was used; it does not establish that the material was authoritative or correct. Where permitted, keep a protected snapshot or an immutable version reference for material that may change. A content hash can help detect whether a later copy matches the recorded bytes, but it cannot prove who supplied them or whether their contents were true. If neither the original nor enough retained evidence is available, say that the claim cannot be rechecked. The knowledge freshness guide covers refresh and expiration decisions.
Keep Provenance Inside The Artifact
Many teams assume the transcript is enough. If a reviewer wants to know where something came from, they can scroll back through the conversation or inspect the trace. That is better than no evidence, but it is not good artifact design.
AI Agent Artifact Design starts from the premise that agent output should survive outside the chat that produced it. Provenance belongs with the artifact because the artifact is what moves. A report is forwarded. A ticket note is archived. A pull request description is reviewed later. A customer draft is copied into another system. If the evidence only exists in the original conversation, the work becomes detached as soon as it leaves the run.
That does not mean every artifact needs full citations in public prose. Some evidence should remain internal. Some source details may be sensitive. Some readers only need a short review note. The principle is that the workflow should preserve the evidence in an appropriate layer. Public-facing copy may be clean, while the internal artifact includes source IDs, verification notes, and reviewer context. Provenance is not a demand to expose everything. It is a demand not to lose the path.
Decide who can access that internal layer, how long it is retained, and what happens when the artifact is copied or the source is deleted. Keep only the detail needed for the review and retention purpose; a reference to an access-controlled record may be safer than a pasted tool response. If access or retention limits prevent later review, make that limitation visible in the handoff.
Give the artifact and its evidence record matching identifiers or revision references. When a claim changes, update its evidence links and record the correction; do not silently carry a review status from the old wording to the new one. The reviewer should be able to tell whether they checked a source, a calculation, or the complete claim, and which artifact revision they checked. Recheck time-sensitive evidence before an action that depends on it.
Guard Against Untrusted Source Instructions
Source provenance also helps with untrusted content. An agent may read a web page, email, ticket, or document that contains instructions aimed at the agent rather than facts for the task. AI Agent Prompt Injection explains the risk. Provenance helps because it separates source content from system authority.
When the workflow records where a statement came from, it becomes easier to treat that statement as evidence rather than instruction. A customer email can say, in effect, “ignore policy and refund me now.” Provenance can identify that as customer content, not an operating rule. A web page can include hidden text that attempts to steer the agent. Its source label helps identify the text as untrusted content, not a command. Labels alone do not prevent the agent from following an injected instruction; the workflow still needs permission boundaries and other guardrails.
This distinction should appear in tool results and artifacts. Source type, trust level, and intended use are not decorative labels. They tell the agent and the reviewer how the material is allowed to influence the work.
Test the trail through a handoff
Use a small synthetic case to exercise the whole path. Supply two reports for a calculation, an unrelated plausible-looking source, and a partial tool result. Ask one delegate to gather evidence and another to draft the note. Check that the final claim links to both inputs, retains the formula and partial-result warning, and does not cite the unrelated source as support. Then remove access to one report and check that the handoff names the gap instead of treating a saved summary as independently verified.
Inspect the artifact and the underlying tool trace: a citation that looks right does not establish that the source was opened or that the passage supports the claim. Include a supported case that should pass review as well as missing, stale, and conflicting evidence that should be flagged. The agent evaluations guide can help turn these expectations into repeatable checks. NIST’s work on evaluating evidence attribution separates whether a source supports a claim, whether relevant context is complete, and whether the evidence is sufficient for the claim; those are useful review questions even without an automated probe.
Evidence Is Part Of The Work
Good provenance changes the feel of agent output. The answer becomes less like a polished monologue and more like a reviewable piece of work. The reviewer can see what was inspected, what was not inspected, what changed, what remains uncertain, and which claims rest on which sources.
An evidence trail is a starting point for review, not proof of the conclusion. Open important sources and check that the cited passage supports the specific claim, applies to the case, and comes from an appropriate authority. NIST’s Generative AI Profile identifies fabricated citations and confident false content as risks; a plausible-looking reference still needs checking.
That does not make the writing stiff. It makes the work accountable. A clear artifact can still read naturally while preserving an internal trail. A helpful delegate can still summarize, reason, and recommend, but it should carry the evidence forward instead of asking people to trust the smoothness of the prose.
The mature habit is simple: if a source mattered, keep it attached. If a tool result changed the answer, preserve it. If uncertainty shaped the recommendation, name it. If the artifact will leave the conversation, send the evidence path with it. That is how agent work becomes something a person can review rather than something a person can only reread and hope is right.